Google’s latest voice AI models can see, listen, reason, and act — all while holding a natural conversation.
Let me show you something.
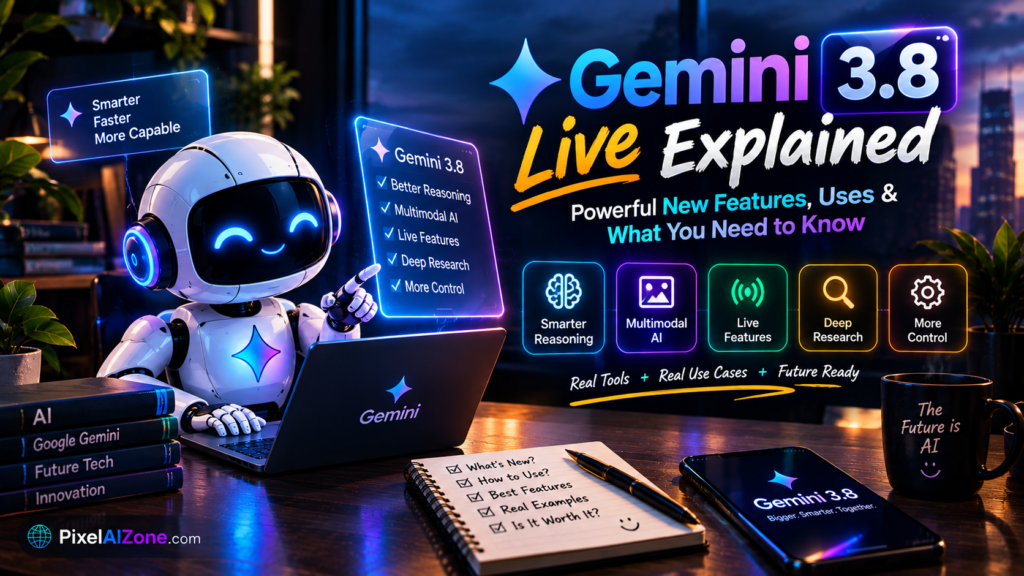
On September 15, 2026, Google released Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking — its most advanced live dialogue models yet . These aren’t just incremental updates. They represent a fundamental shift in what voice AI can do: reason while it talks.
Gemini 3.8 Live explained simply: it’s a native speech-to-speech model that can process visual inputs, execute tool calls in the background, and switch between 97 languages — all without interrupting the conversation .
The Gemini 3.8 Live features are impressive on paper. But what do they actually mean for developers, enterprises, and everyday users? Here’s everything you need to know.
Gemini 3.8 Live explained is essential reading for developers building voice-first AI experiences in 2026.
Table of Contents
- What Is Gemini 3.8 Live?
- The Two Models: Live vs. Extended Thinking
- New Features in Gemini 3.8 Live
- Live Avatar: Visual Presence for Voice Agents
- Real-World Use Cases
- Pricing and Availability
- What You Need to Know Before Building
- FAQ
What Is Gemini 3.8 Live?
This Gemini 3.8 Live explained guide covers every feature you need to know.
Gemini 3.8 Live is Google’s default model for low-latency voice agent experiences and real-time dialogue without reasoning delays . It’s built for scale and cost efficiency, combining conversational intelligence with fluid dialogue and visual grounding .
The key difference from previous models: Gemini 3.8 Live processes visual inputs in near real-time, executes tools and API calls in the background while continuing the conversation, and automatically detects and transitions between 97 supported languages mid-conversation .
On ServiceNow’s EVA-Bench, Google’s models pushed the Pareto Frontier for complex workflows by balancing accuracy with conversational quality . Gemini 3.8 Live also secured second place in the Speech Agent Arena, where humans evaluate AI quality without knowing the model name .
The Two Models: Live vs. Extended Thinking
Google released two models simultaneously, each serving different needs :
Gemini 3.8 Live Extended Thinking ranks #1 on Artificial Analysis’ Speech-to-Speech Quality Index with a score of 82.6, and leads in agentic task completion with 68.6% on τ-Voice .
New Features in Gemini 3.8 Live
Each Gemini 3.8 Live explained feature builds on the last to create a complete voice AI platform.
1. Asynchronous Tool Execution
This is one of the most significant Gemini 3.8 Live features. When the model initiates a tool call, the audio session doesn’t freeze. The agent can provide natural conversational fillers (“Let me pull up your account details…”) and answer follow-up questions while your client executes backend APIs .
Why it matters: Voice agents can now handle complex tasks without awkward silences. The conversation continues while work happens in the background .
2. Visual Grounding
Gemini 3.8 Live processes visual inputs in near real-time (up to 1 frame per second), enriching conversations with context for more helpful responses . It can analyze live images and videos to connect users’ speech with what they see.
Practical example: An insurance claims agent can see damage on camera and fill in the claim notebook automatically as the conversation progresses .
3. 97-Language Support
The model automatically detects and transitions between 97 supported languages mid-conversation without needing session restarts or manual reconfiguration . This includes realistic accents and automatic language switching.
4. Affective Dialogue
Enabled by default in Gemini 3.8 Live, affective dialogue means the model listens to acoustic prosody, emotional cues, pauses, and speech inflection in the user’s audio input, adjusting its vocal tone, empathy, and conversational rhythm naturally .
5. Proactive Audio
The model automatically filters out ambient noise and off-topic background chatter, responding only when addressed directly by the user .
Live Avatar: Visual Presence for Voice Agents
Following the initial Gemini 3.8 Live launch, Google introduced Gemini 3.8 Live with Live Avatar — bringing near real-time visual presence to live dialogue models .
What Live Avatar does:
- Generates video avatars with synchronized lip-syncing at 24 FPS
- Creates natural expressions and fluid turn-taking
- Can be customized from a single reference photo and audio file sample (enterprise allowlisting required)
- Works across web, mobile, and interactive kiosks
Trust and transparency: All generated audio and video streams carry imperceptible SynthID watermarks, ensuring AI-generated content remains detectable to prevent misinformation .
Real-World Use Cases
These Gemini 3.8 Live explained use cases show what’s possible with modern voice AI.
Gemini 3.8 Live explained in practice:
Google’s customers are already innovating with Gemini 3.8 Live. Equal AI handles over a million live calls daily across nine Indian languages, using the model for improved interruption handling, multilingual conversations, and tool-call reliability .
Pricing and Availability
Pricing: Gemini 3.8 Live is competitively priced at $0.005 per minute for audio input** and **$0.018 per minute for audio output .
Session limits: Sessions last up to 15 minutes for audio-only and 2 minutes for audio and video .
Availability:
- Developers: Available in Gemini API and Google AI Studio
- Enterprises: Private preview in Gemini Enterprise, coming soon to Gemini Enterprise for Customer Experience
- Everyone: Available in Search Live
What You Need to Know Before Building
The Live API remains in preview. Google’s broader Live API is still in preview status, which organizations should account for when evaluating integrations and support requirements .
Voice output cannot double as a completion signal. Interfaces and downstream systems should wait for the appropriate state before treating a booking, lookup, or other action as finished — even when the model sounds as though it has already responded .
Hallucinations are possible. Google’s Gemini 3.8 Audio model card states that both models can hallucinate and may occasionally experience slowness or timeouts, making retry, verification, and failure-handling logic important for transactional applications .
FAQ
Q: What is Gemini 3.8 Live?
A: Gemini 3.8 Live is Google’s default model for low-latency voice agent experiences and real-time dialogue. It’s a native speech-to-speech model that processes visual inputs, executes tool calls in the background, and supports 97 languages .
Q: What’s the difference between Gemini 3.8 Live and Extended Thinking?
A: Gemini 3.8 Live is optimized for fast responses and high-volume voice experiences. Extended Thinking is for complex, multistep tasks requiring deeper background reasoning while maintaining conversation .
Q: How much does Gemini 3.8 Live cost?
A: Audio input costs $0.005 per minute and audio output costs $0.018 per minute. Sessions last up to 15 minutes for audio-only .
Q: What is Live Avatar?
A: Live Avatar adds near real-time visual presence to voice agents, generating video avatars with synchronized lip-syncing at 24 FPS. Custom avatars require enterprise allowlisting .
Q: Can Gemini 3.8 Live see what I see?
A: Yes. The model processes visual inputs in near real-time (up to 1 FPS) and can analyze live images and video feeds alongside audio .
Q: Is Gemini 3.8 Live available for everyone?
A: Developers can access it via Gemini API and Google AI Studio. Enterprises have it in private preview in Gemini Enterprise. Everyone can experience it in Search Live .
Final Thoughts
Gemini 3.8 Live explained is more than a model update — it’s a new paradigm for voice AI. The ability to reason while talking, see while listening, and act while conversing represents a fundamental shift in what voice agents can accomplish.
What the Gemini 3.8 Live features deliver:
- Asynchronous tool execution without conversation interruption
- Near real-time visual grounding
- 97-language support with mid-conversation switching
- Affective dialogue that reads emotional cues
- Optional Live Avatar for visual presence
What you need to know:
- The Live API remains in preview
- Voice output isn’t a completion signal
- Hallucinations and timeouts are possible
- Pricing is competitive at $0.005/min input and $0.018/min output
For developers and enterprises building voice-first experiences, Gemini 3.8 Live offers a powerful, cost-effective foundation. The question is no longer whether AI can hold a conversation — it’s what your AI can accomplish while it talks.
Now that you have Gemini 3.8 Live explained, you can start building your first voice agent today.
Related Posts on Pixelaizone
- [AI Coding Agents in 2026: Can AI Build Your Next App?]
- [Best AI Tools for Bloggers in 2026: Write, Research and Rank Faster]
What will you build with Gemini 3.8 Live? Drop a comment below!